Kunnworks

Translation AI, from text to video calls

Build text translation, speech translation, STT or TTS on their own, or combine them in video conversations

Multilingual interpretation for manufacturing
Enterprise AI service · interpretation workflows▷ Screen preview
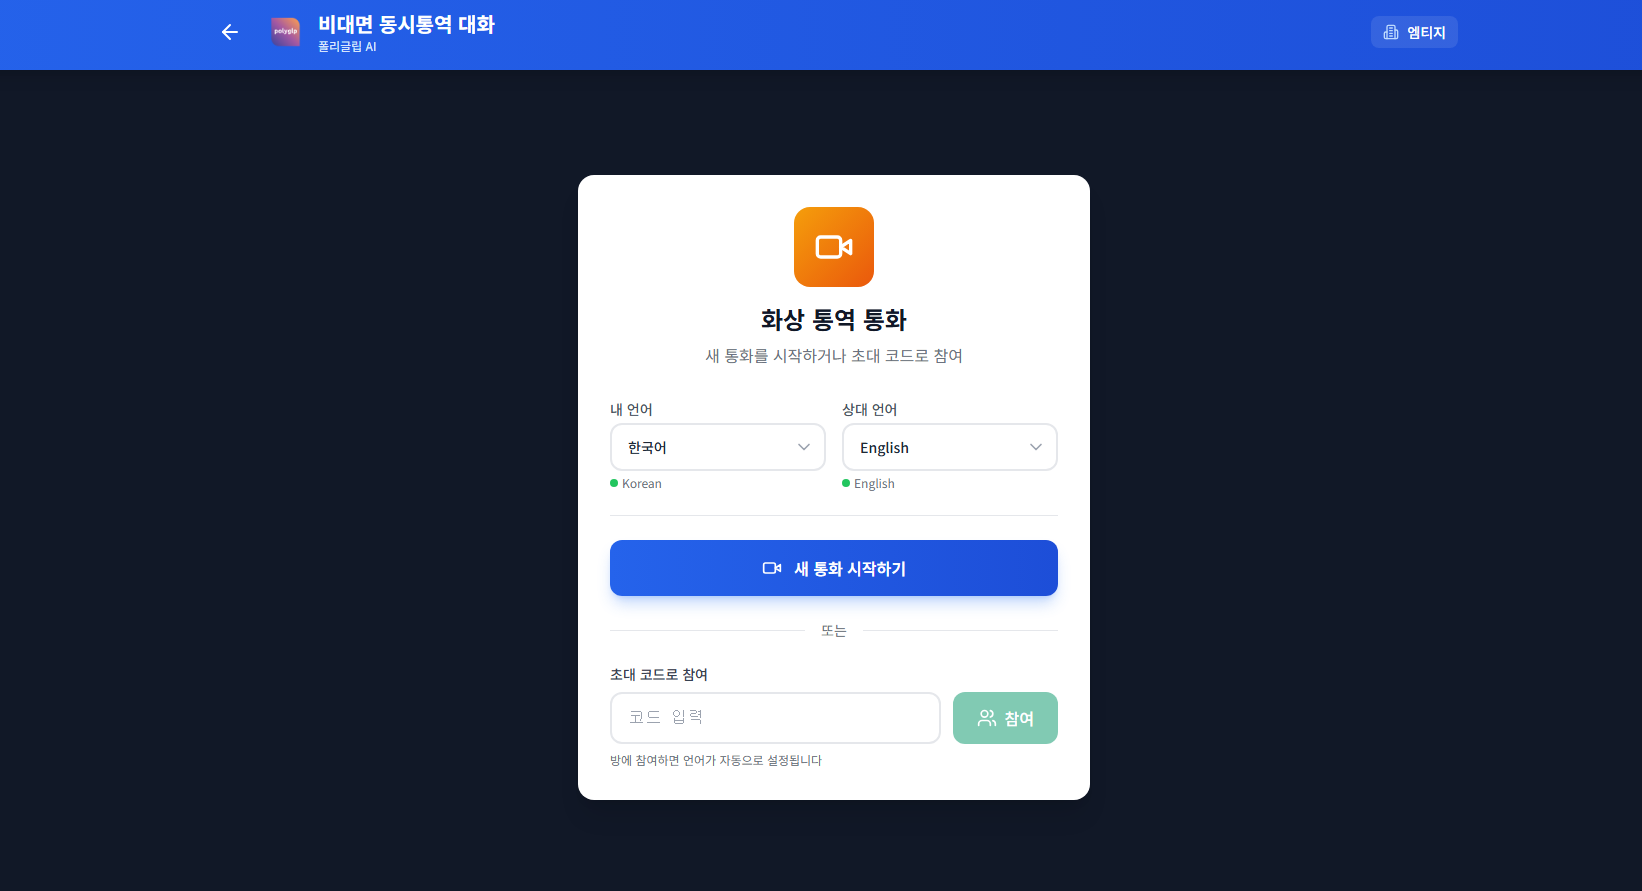
Manufacturing support and multilingual interpretation AIService entry and configuration interfaces
IMPLEMENTATION SCOPE

AI across text, speech and video conversations

Connect STT, translation and TTS to the workflow. Handle language switching, partial results, turn order and connectivity; evaluate with domain terminology and representative conversations.

What we build
Translation UI · STT/TTS · multilingual call/video integration · terminology and quality review
What we validate
Noise, overlapping speech, domain terms, disconnection, latency and playback order
Read the architecture, acceptance scenarios and handover details
IN YOUR EVERYDAY WORK

Design for the conversation,
not just the language.

Before listing features, we define the inputs, decisions and next actions in a real working situation.

An illustrative scenario. Specific processing rules are agreed for the project.

WORKFLOW EXAMPLEILLUSTRATIVE

On-site guidance needs to reach several language groups.

Input
Input language · output languages · conversation mode
Review
Terminology · noise · latency · reconnection
NEXT ACTION

Build interpretation interfaces for broadcasts, in-person or remote work

When this service helps

When customer service, on-site guidance or meetings cross language boundaries

  1. 1

    Choose languages and conversation mode

  2. 2

    Communicate through text, speech or video

  3. 3

    Read captions, hear speech or review transcripts

What the project delivers

  • Agreed translation, STT and TTS modules
  • Conversation, caption and video interfaces
  • Terminology, quality and reconnection checks

Specific features, integrations and operating support are agreed in the project proposal

↗SERVICE CONFIGURATIONS

Individual capabilities
One connected conversation service

Build text translation, speech translation, STT, or TTS independently, or integrate them into video conversations. Scope language support and delivery around the actual operating environment.

01

Text translation

Build translation APIs and review interfaces for documents, chat, product content, and support. Manage terminology, register, named entities, and number formatting by language pair. Link translated segments to their source and preserve review and revision history.

Input
Text, documents, or chat messages
Output
Translations and review history
02

Speech translation

Turn microphone or file audio into translated captions and synthesized speech. Compare an STT → translation → TTS pipeline with direct speech-translation models against the task. Handle utterance boundaries and revisions to intermediate results explicitly.

Input
Live microphone or audio files
Output
Translated captions and speech
03

Standalone STT

Build transcription APIs, tools, and live captions without a translation stage. Define sample-rate and channel normalization, partial versus final results, segment timestamps, and optional speaker diarization. Separating speakers is distinct from identifying who they are.

Input
Microphone, recordings, or call audio
Output
Source transcript and timestamps
04

Standalone TTS

Build speech-generation APIs and playback from source or translated text. Validate provider-specific SSML support, pronunciation dictionaries, number reading, speaking rate, and chunked playback. Cancel queued audio when the text changes or playback is interrupted.

Input
Source text, translations, or structured text
Output
Synthesized audio and streaming playback
05

Multilingual video chat

Connect per-participant language selection, original and translated captions, and optional translated voice to browser or app video calls. Separate the call from translation processing to handle delayed captions, mute, reconnects, and overlapping speech. Design playback routing to avoid feeding translated audio back into recognition.

Input
Participant video and audio tracks
Output
Video calls, captions, and optional interpreted audio

Technical design and acceptance criteria

Details for technical reviewers. Architecture and acceptance criteria are agreed for the actual environment and project scope.

  • Streaming STT
  • Terminology & context
  • TTS / SSML
  • WebRTC

Processing flow and exceptions

Speech passes through recognition, translation, and synthesis. Text can enter translation or TTS directly, while transcripts and translated captions are separate outputs. Video conversations connect each participant’s audio to the same processing flow.

Text, speech, and video translationSpeech passes through recognition, translation, and synthesis. Text can enter translation or TTS directly, while transcripts and translated captions are separate outputs. Video conversations connect each participant’s audio to the same processing flow.Text, speech, and video translationKUNNWORKS · DESIGN EXAMPLEVideo conversationParticipant audioText inputDirect TTS inputAudioinputSTTTranslationTTSTranscript / STT onlyTranslation / subtitlesSpeech / TTS onlyMicrophone, file, or callLink text and audio by segment ID; keep participant languages and playback separate in video calls
TRANSLATION & SPEECH AI / MULTILINGUAL COMMUNICATIONDesign example · Refined against scope and constraints

Architecture summary

  1. Language and quality — Language pairs, glossary, voice, source preservation, review criteria
  2. Real-time processing — Segment IDs, partial/final states, caption timing, cancellation, backpressure
  3. Operations and data — API or private deployment, concurrency, audio/transcript retention, access
02Acceptance criteria

Implementation and acceptance criteria

Concrete design decisions and acceptance scenarios to agree for the project.

Language and quality

ImplementationLanguage pairs, glossary, voice, source preservation, review criteria

ValidationEvaluate names, numbers, noise, accents, and language switches

Real-time processing

ImplementationSegment IDs, partial/final states, caption timing, cancellation, backpressure

ValidationRevised transcripts, overlapping speech, slow consumers, reconnects

Operations and data

ImplementationAPI or private deployment, concurrency, audio/transcript retention, access

ValidationOriginal-call behavior during translation failure, session cancellation, deletion

Technology choices and acceptance criteria depend on discovery, integrations, and agreed scope. We define reproducible acceptance scenarios and handover evidence for the operating environment.

03Implementation details

Engineering decisions
in detail

From visible features to failure conditions,
we work through the decisions before launch.

01

Evaluate translation by language pair and domain

Select models using the actual language pairs and representative documents or conversations. Specify glossary versions, protected strings, number and unit preservation, and context windows. Combine automated evaluation with human review of meaning and terminology. Apply masking and access rules before external API calls; track source revisions so only affected segments need reprocessing.

02

Streaming requires commit points and cancellation rules

Distinguish voice activity, end-of-utterance detection, and partial versus final recognition. Link source segments, translations, and audio chunks through session, utterance, and segment IDs. Update revised captions without replaying committed speech. Standalone STT preserves timestamp and ordering contracts; standalone TTS validates locale, voice, codec, pronunciation, cancellation, and playback-queue behavior.

03

Keep video connectivity separate from AI processing

Define participant and track management, signaling, ICE connectivity, and TURN relay requirements. For group calls, assess an SFU or media server and per-participant audio processing. Caption events carry speaker, language, and segment timing. Keep the original call state distinct from translation availability, and reject stale results after mute, device changes, reconnects, or session cancellation.

04

Turn accuracy, latency, and retention into operating criteria

Evaluate STT with fixed language-specific normalization and tokenization for WER/CER, plus domain-term recognition. Review translation for meaning, numbers, and terminology, and TTS for pronunciation, continuity, and intelligibility. Measure p50/p95 time from utterance end to committed captions and first translated audio, separately from queue delay. Choose API or private deployment against model, language, and concurrency requirements, with explicit recording, transcript-access, and deletion policies.

04Handover

Detailed deliverables

  • Language pairs, modes, glossary, representative evaluation set, and quality/latency criteria
  • Agreed translation, STT, TTS APIs, interfaces or video-call features, and event contracts
  • Sample evaluation results and monitoring, cost, access, retention, and deployment handover
05Before implementation

Questions before implementation

  • Required language pairs and priorities across text, speech, STT, TTS, and video chat
  • Live or file processing, concurrency, and acceptable conversational delay
  • Target app, meeting or support systems, external API use, and audio/transcript retention

How your project moves forward

01

Discover

Understand your goals, workflows, and operating environment.

02

Define

Define features, priorities, and integration requirements.

03

Build

Build the agreed scope and review progress together.

04

Launch & Operate

Prepare testing, deployment, and operational handover.

Let’s discuss your project

Tell us what you want to build or improve
Our team will review your request and reply by email

Discuss your project